上下文並行:可擴展的百萬 Token 推理
原始論文:Context Parallelism for Scalable Million-Token Inference 作者:Amy Yang, Jingyi Yang, Aya Ibrahim, Xinfeng Xie, Bangsheng Tang, Grigory Sizov, Jeremy Reizenstein, Jongsoo Park, Jianyu Huang arXiv ID:2411.01783v2 日期:2024-11-01 標籤:LLM Inference Long Context Parallelism Ring Attention 系統優化
1. 引言
長上下文 LLM 推理面臨兩大瓶頸:prefill 階段的計算量隨上下文長度平方增長,以及 KV cache 的記憶體需求線性增長。本文提出上下文並行 (Context Parallelism, CP),一種系統級優化方法,在不改變模型架構的前提下,將長上下文推理擴展到百萬 token 規模。
核心成果:
- 在 16 台 H100 節點(128 GPU)上,用 Llama3 405B 完成 1M token 的 prefill 只需 77 秒,並行效率 93%,FLOPS 利用率 63%
- 128K 上下文 prefill 只需 3.8 秒
- 提出兩種 ring attention 變體:pass-KV 和 pass-Q,針對不同場景自適應選擇
- 支援多輪對話的持久化 KV cache
2. 方法
2.1 負載均衡分片
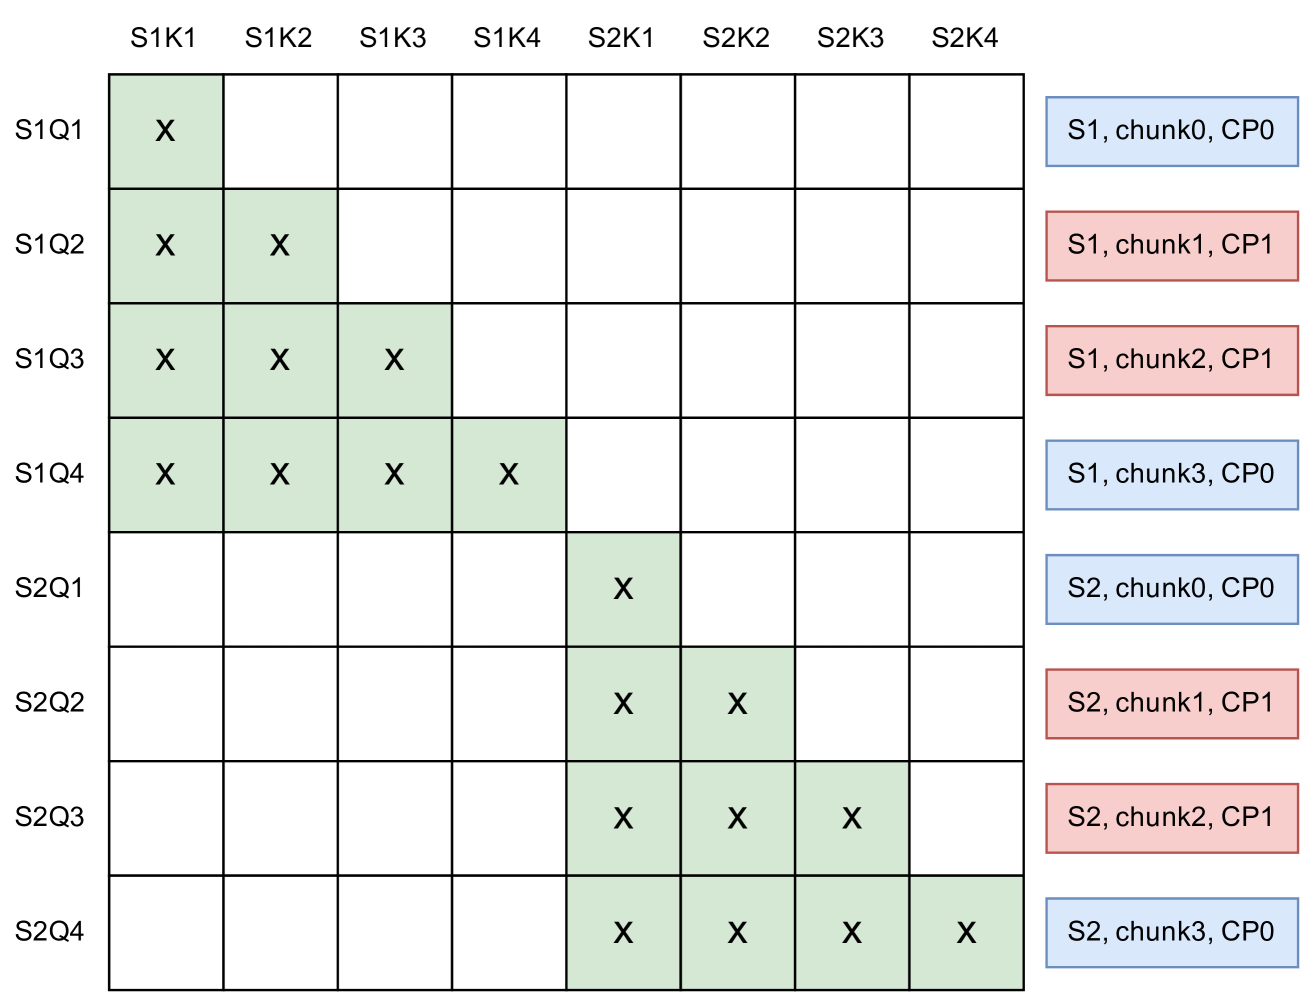
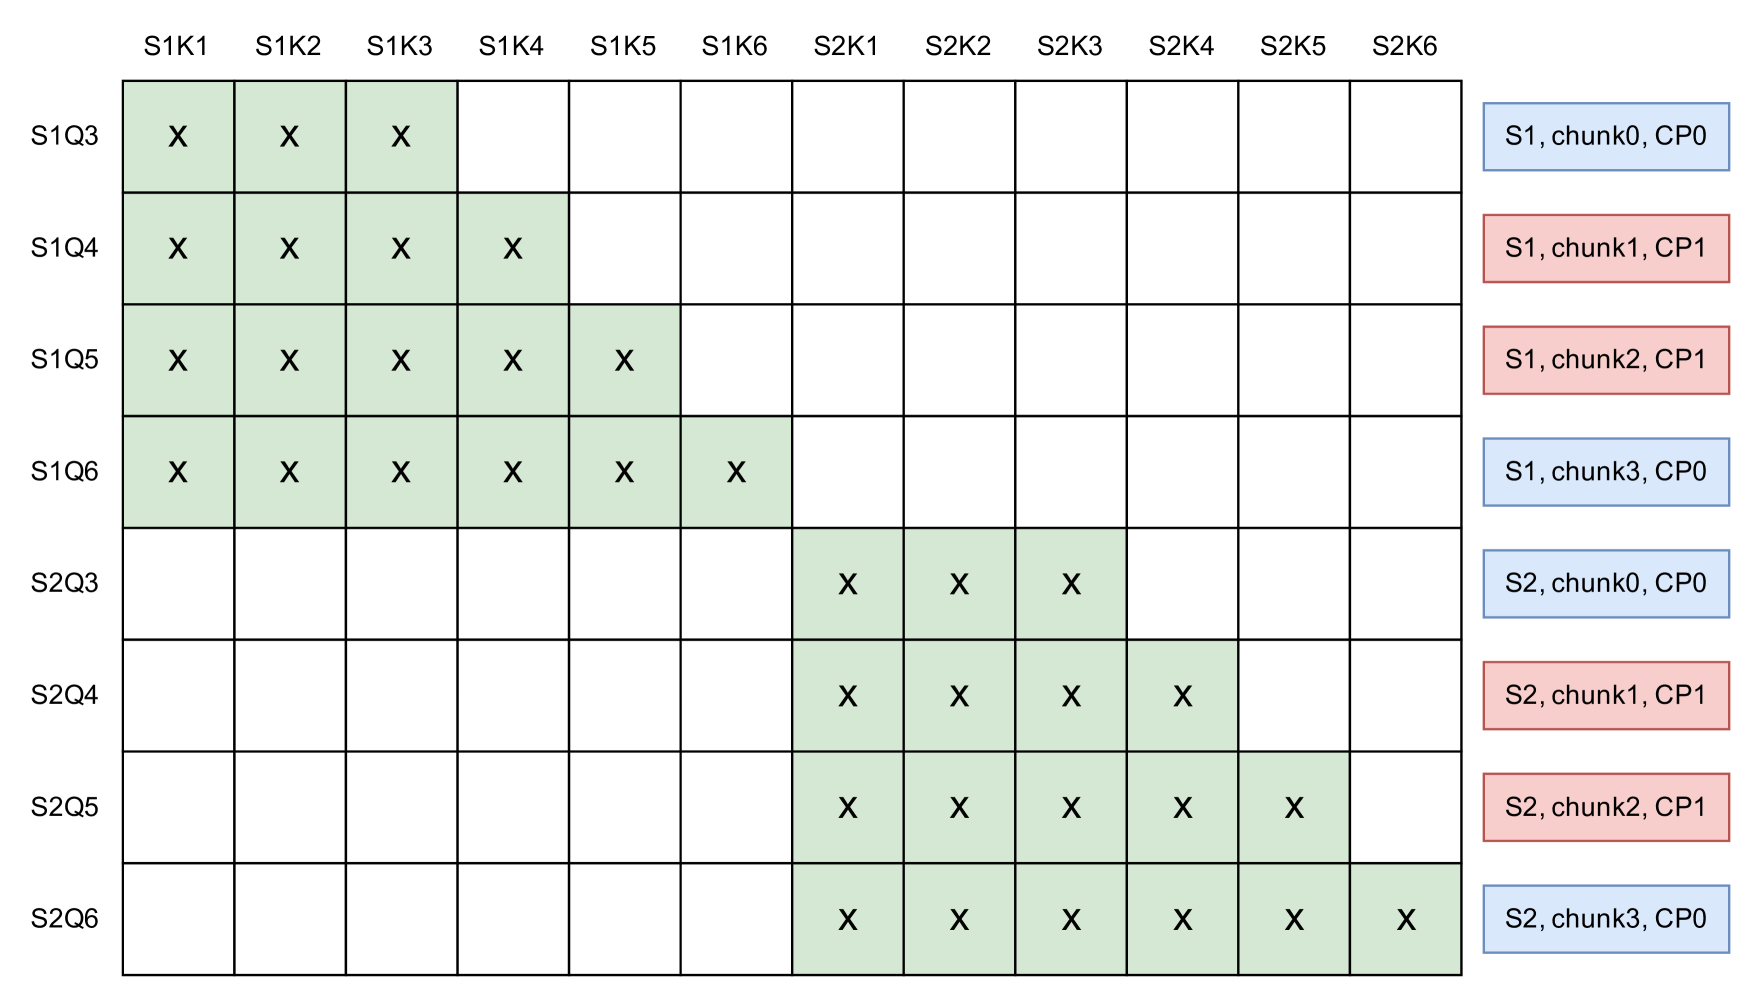
因果注意力 (causal attention) 的三角結構使得序列前端的 token 計算量少於後端。直接按序列位置切分會導致嚴重的負載不均衡。
解法:將序列切成 $2N$ 個 chunk($N$ 為 rank 數量),然後將 chunk $\{C_i, C_{2N-i-1}\}$ 分配給 rank $i$。這樣每個 rank 拿到一個靠前和一個靠後的 chunk,因果注意力的計算量和 KV cache 容量在所有 rank 上均勻分佈。
2.2 Ring Pass-KV 演算法
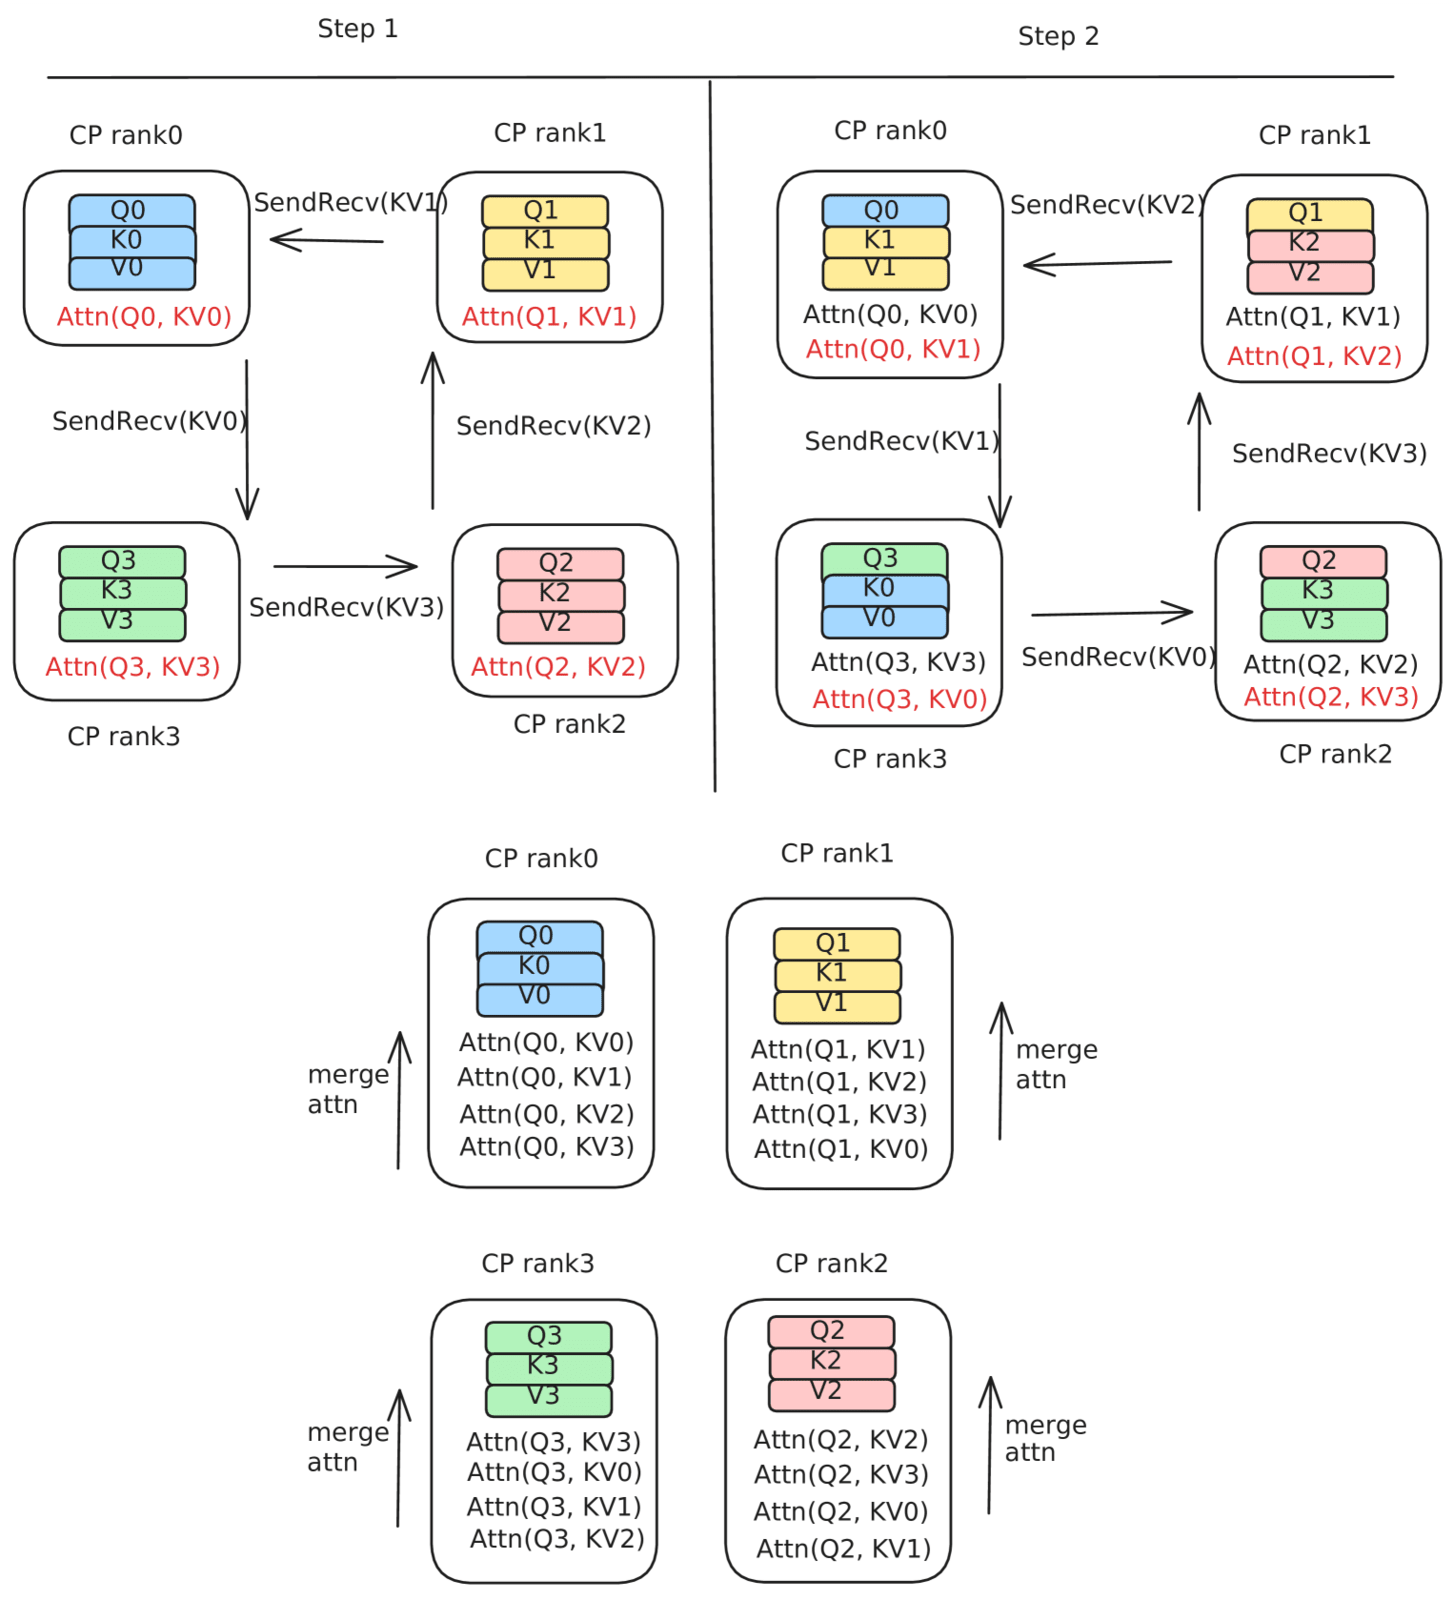
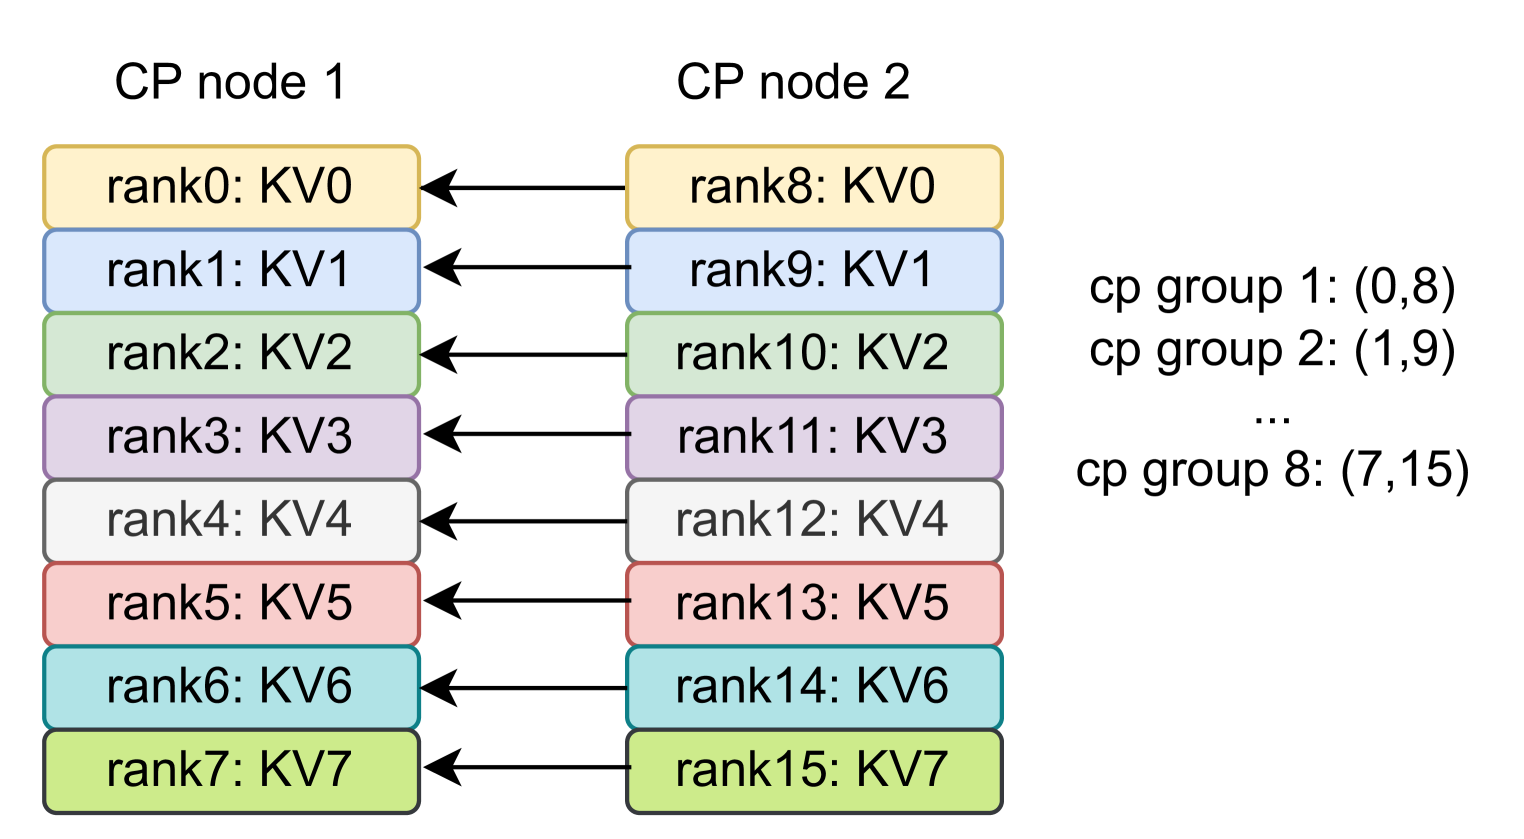
在 prefill 階段,各 rank 的 KV 嵌入以環形方式在相鄰 rank 之間傳遞:
- 串接所有 batch 的 KV 嵌入,padding 到最大長度 $L^i$
- 循環 $N-1$ 次迭代:
- 從前一個 rank 接收 $KV^s$($s = (k-j) \bmod N$)
- 與通訊並行地計算 $\text{GQA}(Q_k, KV^s)$
- 更新 $KV^s$ 為新收到的嵌入
- 合併所有 rank 貢獻的注意力輸出
關鍵特性:保持等大小的訊息用於集合通訊,對 batch 內變長序列的多輪場景很重要。
2.3 Ring Pass-Q 演算法
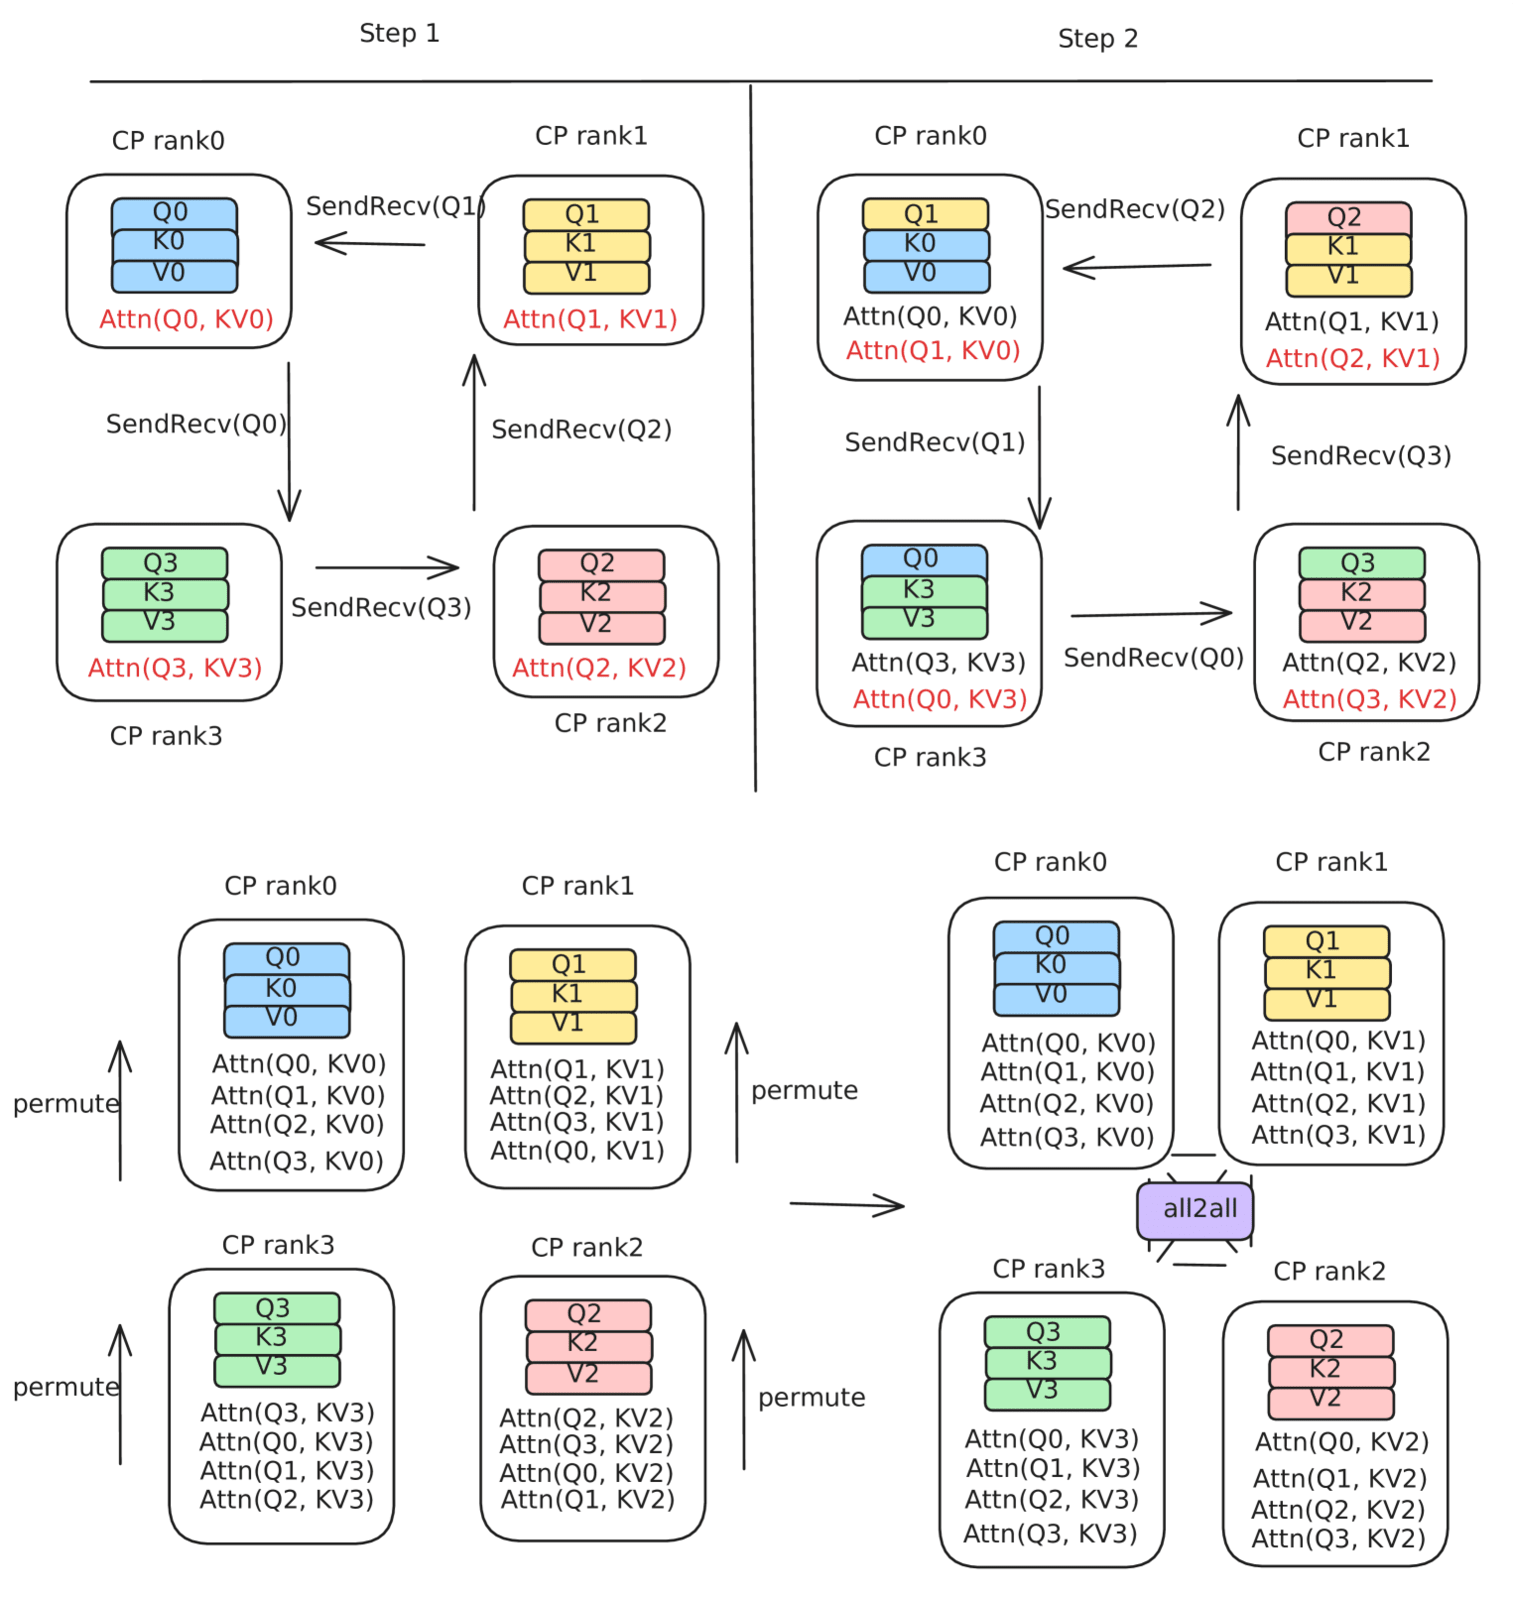
當 Q tensor 較小時(如 partial prefill 或 decode),傳遞 Q 比傳遞 KV 更高效:
- 串接所有 batch 的 Q 嵌入(因負載均衡分片,各 rank 大小相同)
- 循環 $N-1$ 次:
- 將 $Q^s$ 傳送到下一個 rank
- 用本地 K,V 計算 $\text{GQA}(Q^s, KV_k)$
- All2All 排列將部分輸出 $\{O_k^s\}$ 重新分配回源 rank
- 合併注意力結果
2.4 自適應選擇啟發式
根據新 token 數 $T$、已快取 token 數 $P$、CP rank 數 $N$、query 頭數 $N_H$、KV 頭數 $N_{KV}$ 等,動態選擇演算法:
選擇 pass-KV 的條件:
$$\frac{T}{T+P} \geq 2 \cdot \frac{N_{KV}}{N_H}$$
對 Llama3 405B($N_H=128, N_{KV}=8$),閾值為 KV cache miss rate ≥ 12.5%。
通訊重疊條件(pass-KV 可完全隱藏通訊的最小 $T$):
$$T \geq N \cdot \frac{C \cdot N_{KV} \cdot e}{2 \cdot N_H \cdot BW}$$
其中 $C$ 為上下文長度,$e$ 為嵌入大小,$BW$ 為頻寬。
簡言之:miss rate 高(大量新 token)→ pass-KV;miss rate 低(少量新 token + 大量 cache)→ pass-Q。
2.5 多輪對話支援
三個推理階段無縫銜接:
- 完整 prefill($P=0$):首輪用戶 prompt,用 ring pass-KV + 負載均衡 $2N$ chunk 分片
- 部分 prefill($P>0, T>0$):後續輪次的新 token 需注意力到先前輪次的 KV cache。負載均衡分片只對新 token 維度施加。根據啟發式選擇 pass-KV 或 pass-Q
- Decode:每序列生成 1 個新 token,用 ring pass-Q 最小化通訊。輪流 (round-robin) 分片防止 cache 集中
持久化 KV cache 讓 KV 可跨輪次重用,避免重複計算。
3. 實驗結果
硬體平台
- GTT (Grand Teton Training):每 GPU 400 Gb/s RDMA,2.4 TB/s HBM 頻寬
- GTI (Grand Teton Inference):每 GPU 100 Gb/s TCP/IP
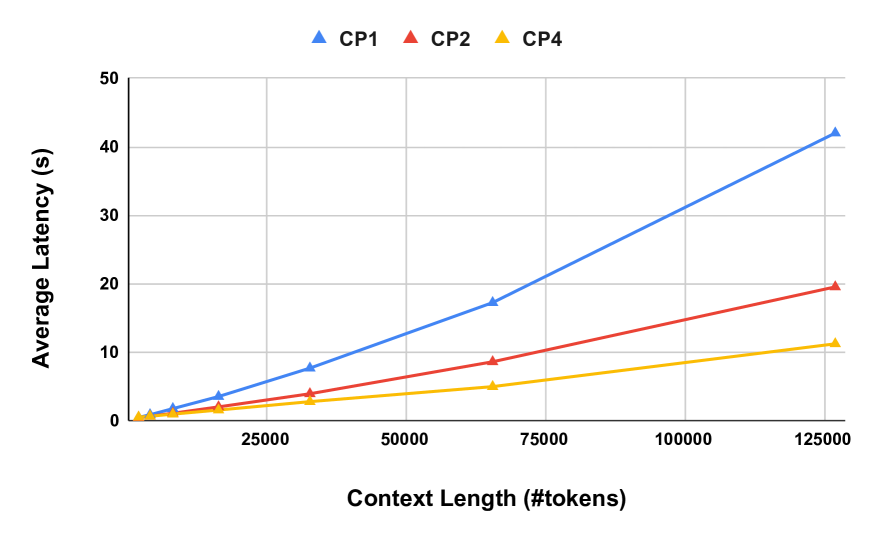
兩個平台都展示了近線性擴展,證明在較低頻寬網路上也能保持可擴展性。
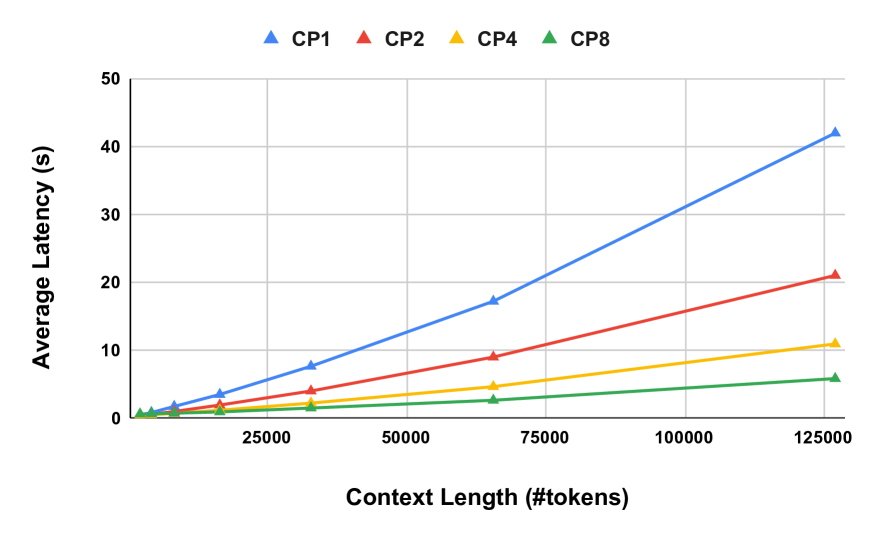
Prefill 效能
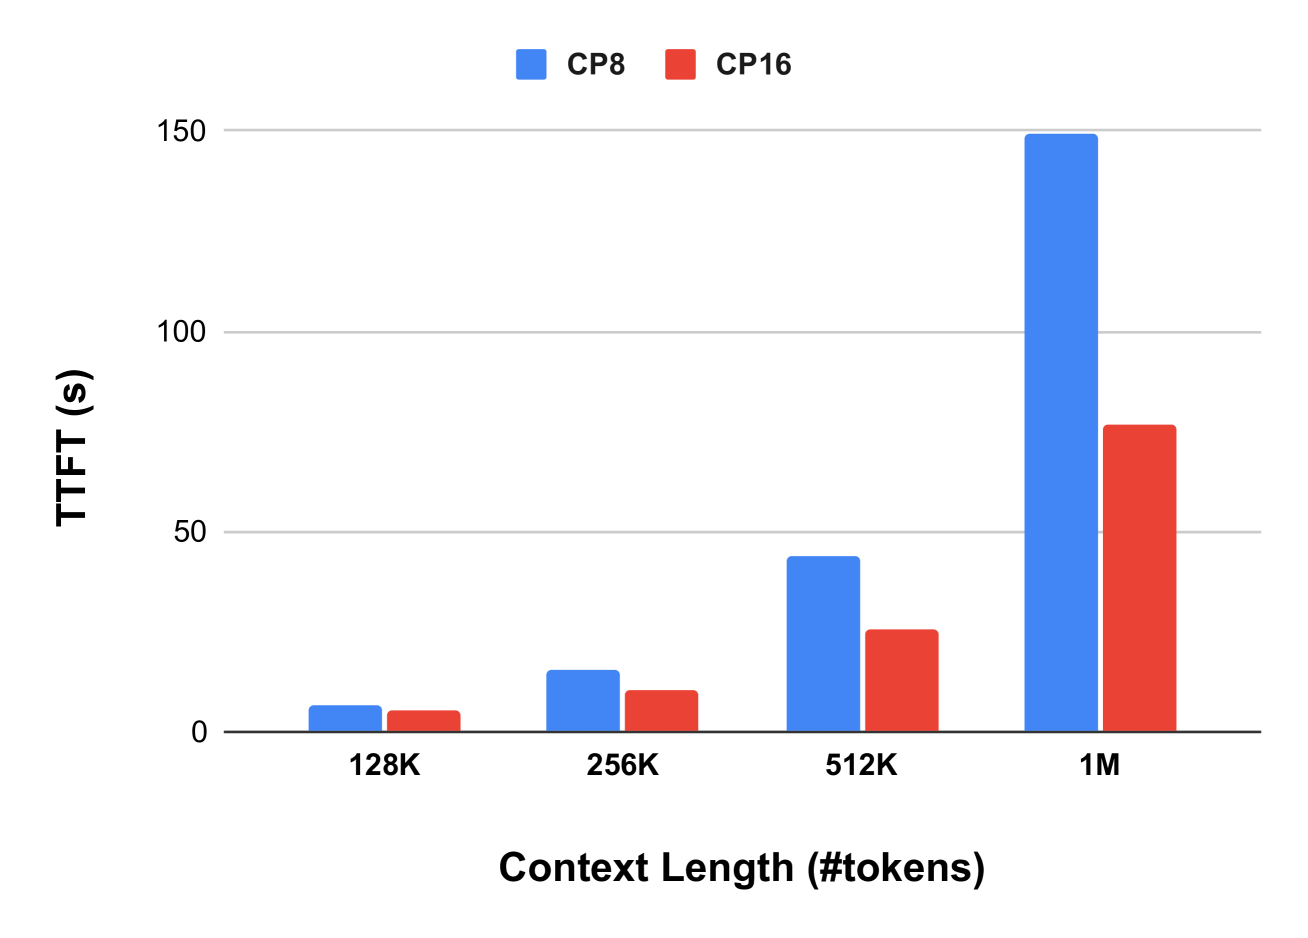
Llama3 405B 在不同上下文長度和 CP 規模下的 prefill 延遲:
- 1M token:77 秒(CP16,128 GPU),並行效率 93%
- 128K token:3.8 秒(CP16);5.85 秒(CP8,GTT)
- 每倍增節點數,延遲近似減半
Decode 效能
| 上下文長度 | TP8 TTFT | CP2+TP8 TTFT | TP8 TTIT | CP2+TP8 TTIT |
|---|---|---|---|---|
| 8K | 1740ms | 999ms | 44.51ms | 65.61ms |
| 32K | 7658ms | 4015ms | 44.64ms | 65.66ms |
| 128K | 42010ms | 21042ms | 46.26ms | 66.63ms |
CP2+TP8 將首 token 時間 (TTFT) 減半,但 inter-token 延遲 (TTIT) 略增(~47%),因為 decode 階段每步只有 1 個 token,通訊開銷的佔比更高。
持久化 KV Cache
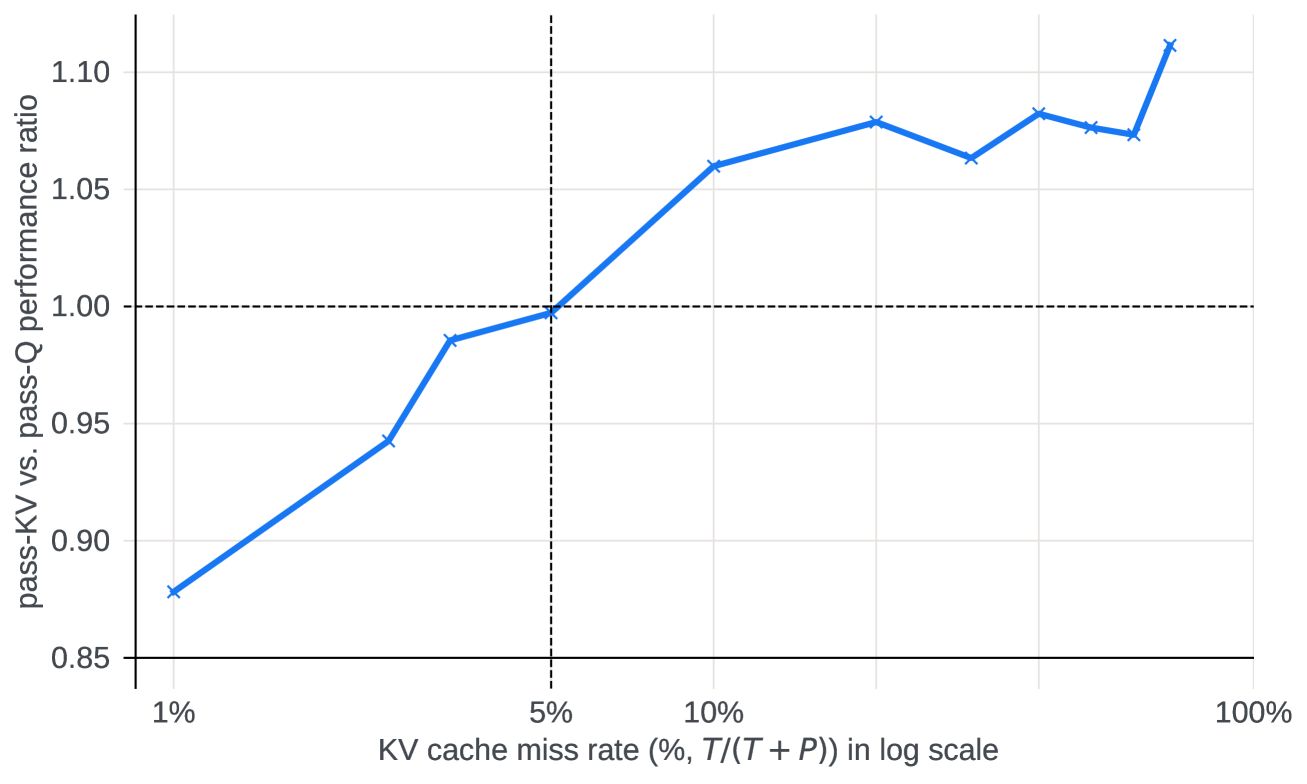
不同 miss rate 下 pass-KV vs. pass-Q 的延遲比較(128K 上下文,CP2):
| Miss Rate | Pass-KV | Pass-Q | 較優 |
|---|---|---|---|
| 1% | 1023ms | 898ms | Pass-Q 快 12.1% |
| 5% | 1302ms | 1305ms | 幾乎相同 |
| 10% | 2080ms | 2205ms | Pass-KV 快 5.7% |
| 50% | 6845ms | 7367ms | Pass-KV 快 7% |
驗證了自適應選擇啟發式的正確性:低 miss rate 時 pass-Q 較優,高 miss rate 時 pass-KV 較優。
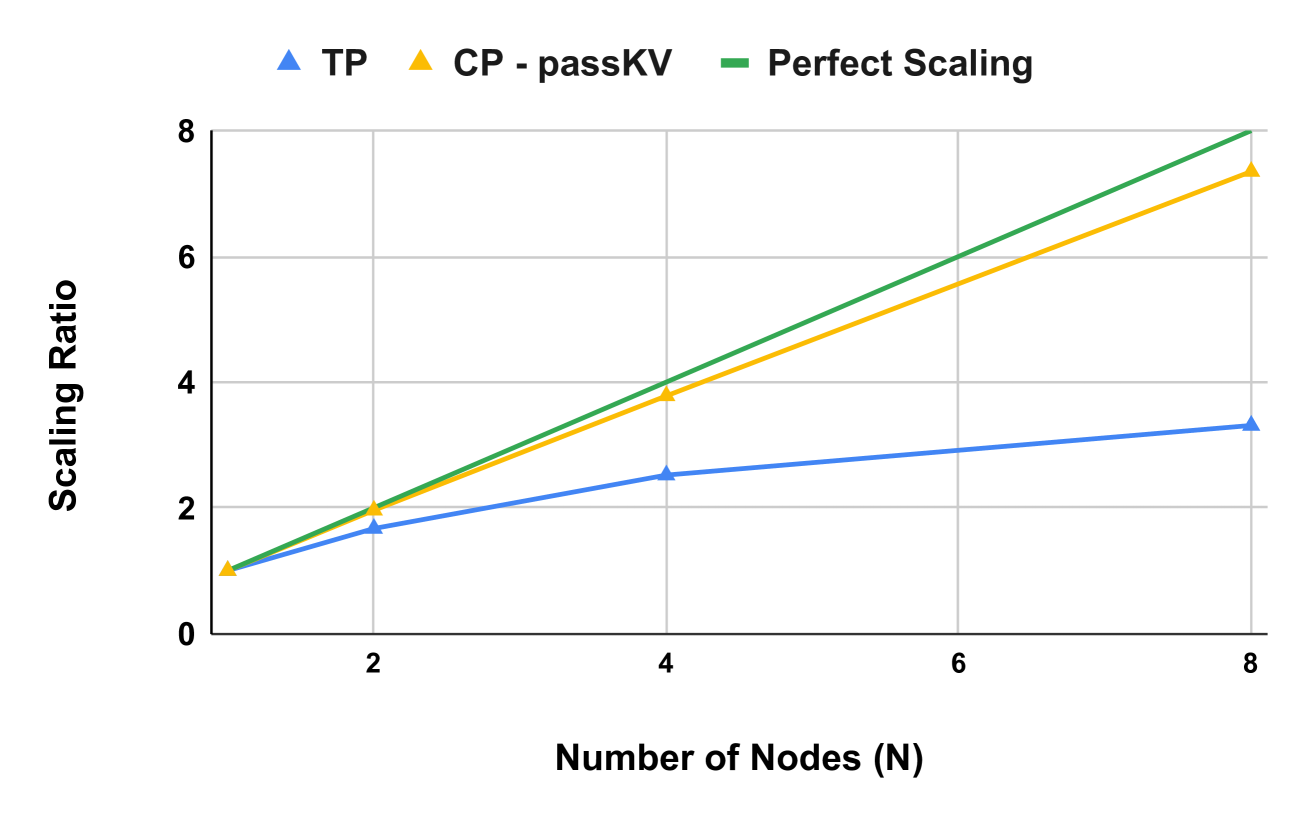
CP vs. TP 的擴展比較
在多節點場景下,上下文並行顯著優於張量並行 (tensor parallelism)。8 節點時 CP 比 TP 有約 100% 的延遲優勢,因為 CP 的跨節點通訊需求遠低於 TP。
4. 結論
上下文並行是一種保持模型架構不變的系統級優化,透過兩種 ring attention 變體(pass-KV 和 pass-Q)和負載均衡分片,實現了長上下文推理的近線性擴展。在 Llama3 405B 上,1M token 的 prefill 只需 77 秒(128 GPU),並支援多輪對話的持久化 KV cache。
參考文獻
Achiam, J., et al. GPT-4 Technical Report, 2023.
Ainslie, J., et al. GQA: Training Generalized Multi-Query Transformer Models from Multi-Head Checkpoints, 2023.
Beltagy, I., Peters, M.E., and Cohan, A. Longformer: The Long-Document Transformer, 2020.
Brandon, W., et al. Striped Attention: Faster Ring Attention for Causal Transformers, 2023.
Brown, T.B. Language Models are Few-Shot Learners, 2020.
Cho, M., Rastegari, M., and Naik, D. KV-Runahead: Scalable Causal LLM Inference by Parallel Key-Value Cache Generation, 2024.
Chowdhery, A., et al. PaLM: Scaling Language Modeling with Pathways. JMLR, 2023.
Dao, T. FlashAttention-2: Faster Attention with Better Parallelism and Work Partitioning, 2023.
Dao, T., Fu, D., Ermon, S., et al. FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness. NeurIPS, 2022.
Devlin, J. BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding, 2018.
Gemini Team. Gemini: A Family of Highly Capable Multimodal Models, 2023.
Gemini Team. Gemini 1.5: Unlocking Multimodal Understanding Across Millions of Tokens of Context, 2024.
Hooper, C., et al. KVQuant: Towards 10 Million Context Length LLM Inference with KV Cache Quantization, 2024.
Huang, Y., et al. GPipe: Efficient Training of Giant Neural Networks Using Pipeline Parallelism. NeurIPS, 2019.
Jiang, H., et al. MInference 1.0: Accelerating Pre-Filling for Long-Context LLMs via Dynamic Sparse Attention, 2024.
Juravsky, J., et al. Hydragen: High-Throughput LLM Inference with Shared Prefixes, 2024.
Kaplan, J., et al. Scaling Laws for Neural Language Models, 2020.
Korthikanti, V.A., et al. Reducing Activation Recomputation in Large Transformer Models. MLSys, 2023.
Kwon, W., et al. Efficient Memory Management for Large Language Model Serving with PagedAttention. SOSP, 2023.
Li, S., et al. Sequence Parallelism: Long Sequence Training from System Perspective, 2021.
Lin, Y., et al. QServe: W4A8KV4 Quantization and System Co-Design for Efficient LLM Serving, 2024.
Liu, H., Zaharia, M., and Abbeel, P. Ring Attention with Blockwise Transformers for Near-Infinite Context, 2023.
Llama Team. The Llama 3 Herd of Models, 2024.
Milakov, M. and Gimelshein, N. Online Normalizer Calculation for Softmax, 2018.
Munkhdalai, T., Faruqui, M., and Gopal, S. Leave No Context Behind: Efficient Infinite Context Transformers with Infini-Attention, 2024.
Narayanan, D., et al. Efficient Large-Scale Language Model Training on GPU Clusters Using Megatron-LM. SC21, 2021.
Qin, R., et al. Mooncake: A KVCache-Centric Disaggregated Architecture for LLM Serving, 2024.
Shah, J., et al. FlashAttention-3: Fast and Accurate Attention with Asynchrony and Low-Precision, 2024.
Shazeer, N. Fast Transformer Decoding: One Write-Head is All You Need, 2019.
Shoeybi, M., et al. Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism, 2019.
Vaswani, A., et al. Attention is All You Need. NeurIPS, 2017.
Xiao, G., et al. Efficient Streaming Language Models with Attention Sinks, 2023.
Zhong, Y., et al. DistServe: Disaggregating Prefill and Decoding for Goodput-Optimized LLM Serving, 2024.
術語對照表
| 英文 | 中文 |
|---|---|
| Context Parallelism (CP) | 上下文並行 |
| Tensor Parallelism (TP) | 張量並行 |
| Ring Attention | 環形注意力 |
| Pass-KV | 傳遞 KV(環形) |
| Pass-Q | 傳遞 Q(環形) |
| Load-Balanced Sharding | 負載均衡分片 |
| Prefill | 預填充 |
| Decode | 解碼 |
| Time to First Token (TTFT) | 首 token 時間 |
| Time per Inter-Token (TTIT) | token 間延遲 |
| KV Cache | 鍵值快取 |
| Persistent KV Cache | 持久化 KV 快取 |
| Grouped Query Attention (GQA) | 分組查詢注意力 |
| Causal Attention | 因果注意力 |
| Multi-turn Conversation | 多輪對話 |
| Parallelization Efficiency | 並行效率 |
| All2All | 全對全通訊 |
| SendRecv | 收發通訊 |
| Miss Rate | 未命中率 |
| RDMA | 遠端直接記憶體存取 |